
PARIS — Delivering a monumental leap for open-weight artificial intelligence, French pioneer Mistral AI has officially released the downloadable weights for its flagship trillion-parameter frontier architecture, Mistral Large 4 (affectionately codenamed "Le Chonk"). Following an intensive three-week post-preview reinforcement learning regimen, the open-weight release establishes Mistral Large 4 as the most powerful openly available Mixture-of-Experts (MoE) foundation model in existence, packing 1.05 trillion total parameters, 52 billion active parameters per token, a native 1-million-token context window, and an unprecedented 82% score on live cybersecurity vulnerability patching where closed proprietary models refuse to participate.
- • Sparse MoE Efficiency: Activates only ~52 billion parameters out of 1.05 trillion per forward pass, maintaining rapid token throughput on high-density HGX nodes.
- • Cybersecurity Dominance: Hits 82% on the Artificial Analysis Cyber Index, safely reproducing and synthesizing fixes for zero-day vulnerabilities without restrictive safety refusals.
- • Selectable Reasoning Modes: Integrates dynamic Low, Medium, and High reasoning effort flags, giving developers granular control over latency budgets and chain-of-thought depth.
Sparse Mixture-of-Experts: Why 52B Active Parameters Matter
Dense foundation models above 500 billion parameters require enormous memory bandwidth and introduce severe latency penalties during multi-turn coding sessions. Mistral Large 4 avoids this bottleneck by implementing a refined sparse Mixture-of-Experts routing topology. While the full model weights span 1.05 trillion parameters stored across tensor-parallel ranks, each incoming token dynamically activates only two expert subnetworks totaling approximately 49 to 52 billion active parameters.
This architectural choice delivers two critical advantages: first, raw mathematical capability and factual recall scale with the 1-trillion-parameter knowledge base; second, inference memory throughput scales strictly with the 52B active footprint. In production testing across 8x NVIDIA H200 and Blackwell B200 SXM nodes, Mistral Large 4 achieved generation speeds exceeding 64 tokens per second under standard FP8 quantization, rivaling dense 70B models in operational responsiveness.
| Model & Release Tier | Active / Total Params | Terminal-Bench 4.0 | Cyber Index (Defenders) | License Architecture |
|---|---|---|---|---|
| Mistral Large 4 ("Le Chonk") | 52B / 1.05T MoE | 41.8% | 82.0% | MEOW (Open Weights) |
| Alibaba Qwen3-Coder | Dense 480B | 42.4% | 48.2% | Apache 2.0 |
| DeepSeek-V3 Coder | 37B / 671B MoE | 39.6% | 44.1% | MIT License |
| Closed Frontier Baseline | Undisclosed Dense | 44.5% | Refused (< 5%) | Proprietary API Only |
Unlocking Defensive Cybersecurity Without Safety Refusals
A persistent frustration for enterprise red teams and defensive security engineers has been the over-eager alignment guards of commercial frontier models. When tasked with reproducing memory corruption bugs, inspecting decompiled buffer overflows, or formulating automated kernel patches, closed API endpoints frequently reject prompts with generic safety policy violations.
Mistral AI trained Mistral Large 4 with a nuanced distinction between offensive exploitation and defensive remediation. By prioritizing actionable patch synthesis, the model achieved a record-breaking 82% resolution rate on the Artificial Analysis Cyber Index. Security analysts can prompt the model with raw C/C++ memory traces, allowing Le Chonk to autonomously localize pointer overflows, generate unit test reproducers, and output memory-safe Rust rewrites without refusal friction.
# 1. Pull the model weights from Hugging Face
huggingface-cli download mistralai/Mistral-Large-4-1T-A52B --local-dir ./mistral-large-4

# 2. Launch high-throughput tensor-parallel inference (8x GPU)
vllm serve ./mistral-large-4 \
  --tensor-parallel-size 8 \
  --max-model-len 32768 \
  --quantization fp8 \
  --reasoning-effort high \
  --port 8000
Architectural Pros & Sovereign Strengths
- 100% On-Premise Air-Gap Ready: Can be hosted entirely within sovereign enterprise boundaries, complying with strict EU AI Act and GDPR localization laws.
- Unmatched Defensive Utility: Evaluates live exploit code and synthesizes security patches without over-zealous refusal guardrails.
- Extreme Context Handling: Native 1-million-token context window ingests entire enterprise codebases and regulatory filings simultaneously.
Operational Trade-Offs & Hardware Demands
- Substantial VRAM Requirements: Despite 52B active routing, storing the 1.05T parameter weights in FP8 requires minimum 8x 80GB/141GB GPUs.
- MEOW License Restrictions: The Mistral Ecosystem Open-Weight license allows internal corporate use, but bars commercial third-party API reselling.
- Quantization Degradation: Aggressive 4-bit quantization degrades complex multi-step reasoning depth compared to FP8/BF16 baselines.
The Verdict for Enterprise Engineers
Mistral Large 4 cements Europe's leadership in sovereign open-weight frontier modeling. By refusing to compromise on defensive security utility and pairing a 1.05T knowledge base with 52B active routing, Mistral provides technical leaders with a viable, self-hostable alternative to closed US cloud APIs that excels precisely where corporate security demands it most.
Hugging Face Weights Repository & Documentation
Access the official open-weights repository, model card, and deployment instructions on Hugging Face.
Explore AI Models & Autonomous Tools
Benchmark, compare, and discover verified tools powering the new wave of frontier reasoning and autonomous software engineering.

AUTHORED BY
Hamza Khaliq
Student, Author, Learner, Developer and Researcher
Covering the latest AI developments and industry news.
More news you might like

Factory Releases Droid 1.0 Establishing Programmatic Tool Calling as Default Standard
Factory has launched Droid 1.0, shifting coding agent architectures to Programmatic Tool Calling (PTC) by default and achieving 65.2% on Terminal-Bench 4 while ending turn-by-turn API bloat.
Vercel Labs Open-Sources Agent Desktop Replacing Vision Screenshots with Accessibility Trees
Vercel Labs has open-sourced agent-desktop, a high-speed Rust tool allowing autonomous AI agents to interact with desktop apps via OS accessibility trees instead of heavy vision screenshots.
OpenAI Deploys OpenAI Frontier with ADNOC for Autonomous Subsurface Energy Optimization
At ADIPEC 2026 in Abu Dhabi, OpenAI CEO Sam Altman and UAE leadership announced the first global energy enterprise deployment of OpenAI Frontier, using interconnected agent networks to compress field planning from months to hours.
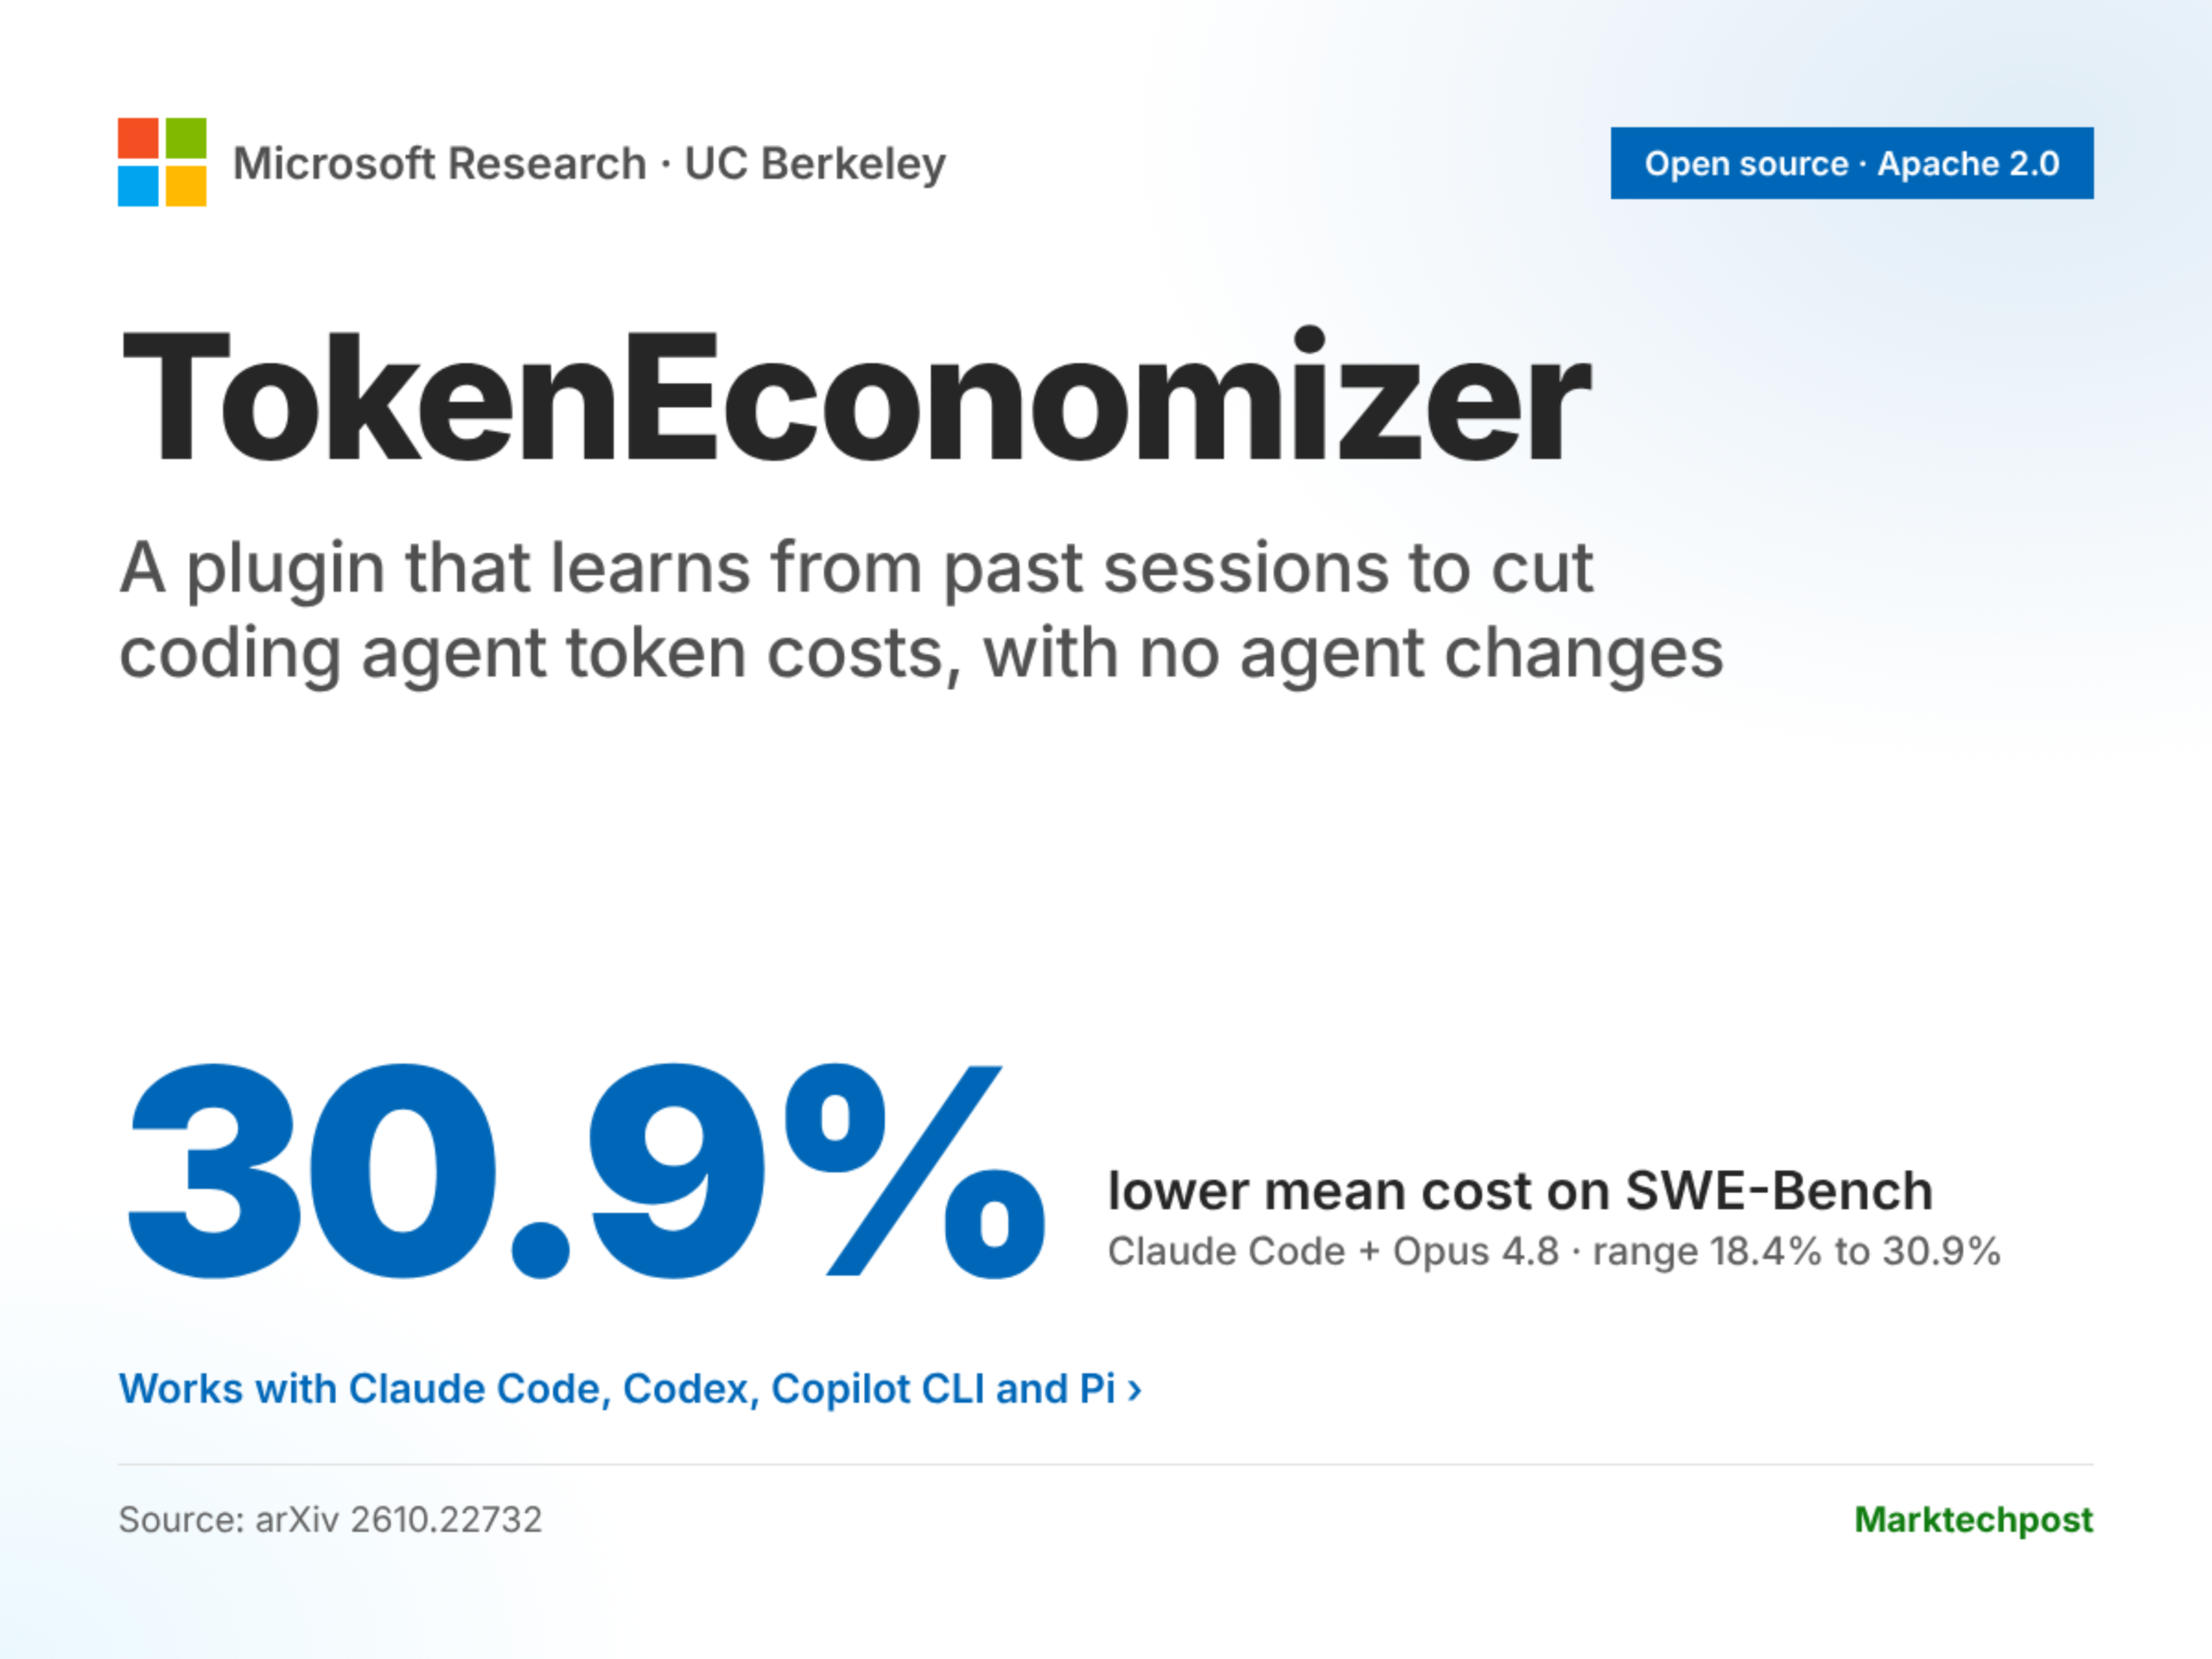
Microsoft Releases TokenEconomizer Slashing Coding Agent Costs by ~31%
Microsoft Research and UC Berkeley have launched TokenEconomizer, an open-source optimization plugin that slashes coding agent token consumption by up to 30.9% on SWE-bench without altering model weights.