
DeepSeek
Open-weight reasoning and coding models with a very low-cost API, from Hangzhou-based DeepSeek
Gallery
8 items
About DeepSeek
DeepSeek is best judged as a model family you plug into other tools, and the practical test is how it behaves as the backend for a coding agent. Setup is the easy part: the API is OpenAI-compatible, and tools like Aider and Cline accept it with a base URL and key. The official pricing page lists V4.1-Flash at $0.15 per million input tokens on a cache miss and $0.60 per million output tokens at off-peak rates, with V4-Pro at $0.66 and $1.98, which is far below typical frontier-model pricing. These notes come from the vendor's documentation and public coverage, not from a controlled benchmark run. The strengths are price, open weights and a 1M-token context window. Coverage of the V4 release reports MIT-licensed weights, so teams can self-host or distill them. The limits are operational. The hosted service runs from China, so organizations with data-residency or compliance rules should review that or self-host, and the largest V4-Pro model, at about 1.6 trillion parameters, is out of reach for local use. Peak and off-peak pricing, frequent model renames and the fact that the main site no longer presents a separate Coder product also mean integrations need upkeep. For cost-sensitive coding agents, batch jobs and research on open weights, DeepSeek is one of the first models to try. Teams with strict compliance requirements should self-host or pick a US- or EU-hosted provider of the open weights instead, and anyone who needs the newest agentic coding behavior should compare it against Qwen3-Coder and the frontier closed models.
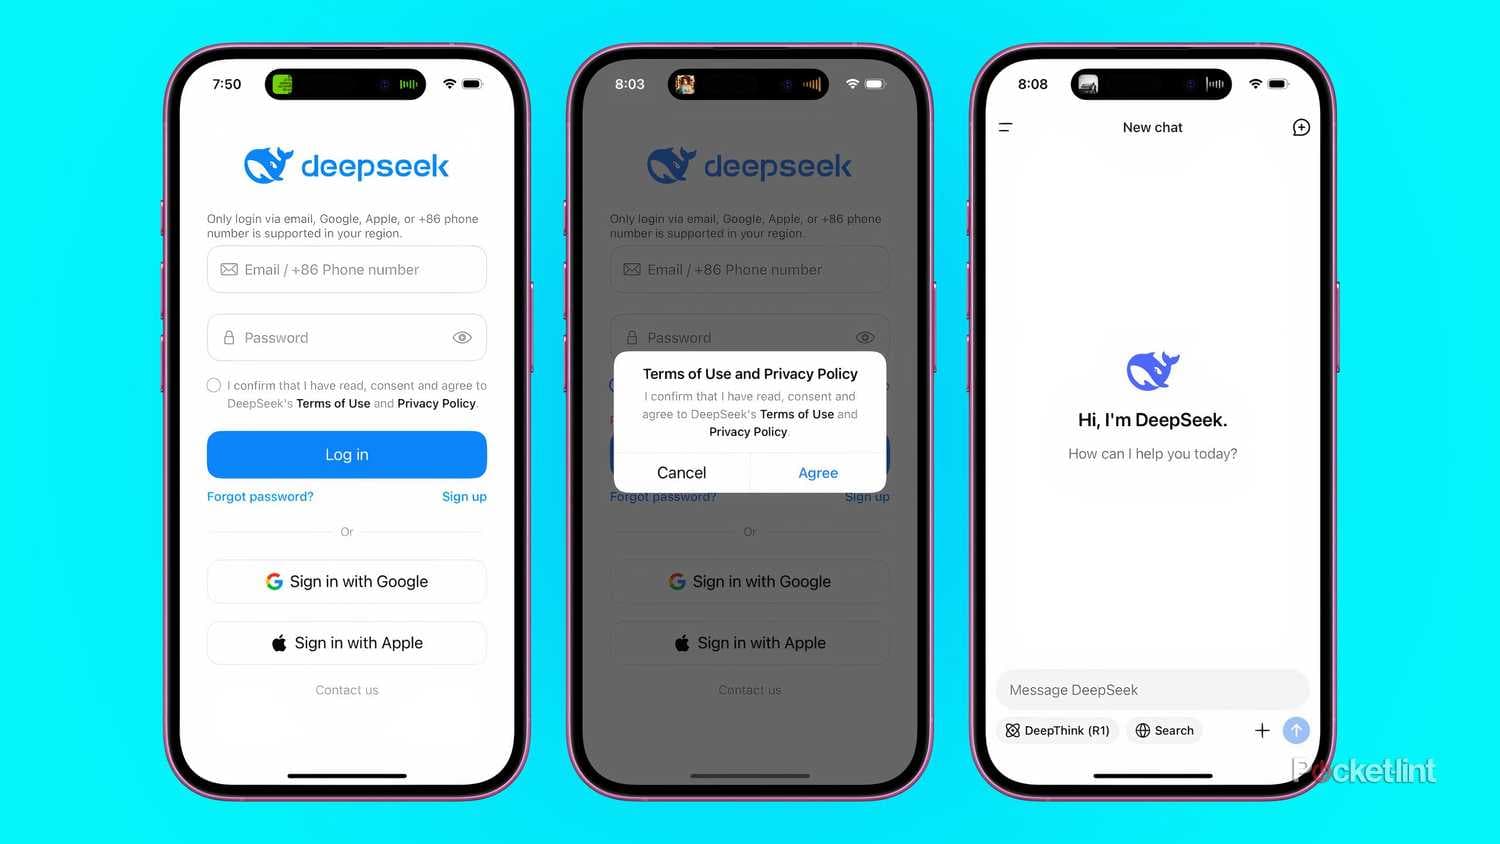
DeepSeek is a Hangzhou-based AI lab that builds and open-sources general-purpose foundation models. Its current lineup includes the V4 family (V4-Pro and V4-Flash, with a 1M-token context window), the earlier V3.x releases and the R1 reasoning model, and it is reachable through a free web chat, mobile app, desktop app and a paid API. Per the V4 release coverage, the open weights are published under the MIT license.
For developers, the draw is strong coding and reasoning performance at a fraction of typical frontier-model prices. The official API lists V4.1-Flash and V4-Pro with per-million-token pricing, a cache-hit discount and half-price off-peak hours. The models are widely used as the backend for open-source coding agents such as Aider and Cline, and as local or self-hosted models. The earlier DeepSeek-Coder line was a dedicated code model; today the main site presents the general V4, V3 and R1 models rather than a separate Coder product.
It suits developers and teams who want cheap, capable models for coding agents, researchers who want open weights they can self-host or fine-tune, and anyone comparing frontier-class models on cost. Teams with strict data-residency or compliance needs should review where the hosted service processes data, or self-host the open weights instead.
Key Features
- V4-Pro and V4-Flash mixture-of-experts models with a 1M-token context window
- R1 reasoning model with step-by-step chain-of-thought
- Strong coding performance used as a backend by Aider, Cline and similar agents
- Open weights, reported as MIT-licensed, for local and self-hosted use
- Pay-as-you-go API with cache-hit discounts and half-price off-peak hours
- Free web chat, mobile app and desktop app
- Search and Fetch tools available through the API
- DeepSeek Harness desktop app for agent workflows
Pros
- Very low API prices compared with other frontier-class models
- Open weights that can be self-hosted, fine-tuned or distilled
- Strong coding and reasoning results, widely used with open-source coding agents
- 1M-token context on the current V4 models
- Free web and mobile apps for casual use
Cons
- Hosted service is operated from China, which can be a data-residency or compliance concern for some organizations
- The full V4-Pro model is too large to run locally for most people
- Model names, versions and prices change frequently, so integrations need maintenance
- Peak-hour pricing and rate limits can affect heavy production workloads
- Official documentation is lighter than that of larger US platforms
Pricing
DeepSeek's web chat and apps are free to use, and the open model weights can be downloaded and self-hosted at no license cost. The API is pay-as-you-go with no subscription.
Per the official API pricing page, deepseek-flash (V4.1-Flash) costs $0.15 per million input tokens on a cache miss and $0.60 per million output tokens at off-peak rates, rising to $0.30 and $1.20 at peak. deepseek-v4-pro costs $0.66 input and $1.98 output off-peak, and $1.32 and $3.96 at peak. Cache-hit input is far cheaper, from $0.003 to $0.044 per million tokens. Both models offer a 1M-token context window. Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays; all other times are off-peak at half price.
Search and Fetch tools cost $0.75 per 1,000 successful requests. The page says calls made through DeepSeek Harness, Claude Code or Codex are free for now, with billing starting November 1, 2026. Prices and model names change often, so check the official pricing page before budgeting.
Claim Verified Creator Badge
Are you the founder of DeepSeek? Display this listing's verified badge on your website to show your customers that your product has been vetted and listed on AI Central Resources.
<a href="https://www.aicentralresources.com/tool/deepseek" target="_blank" rel="noopener">
  <img src="https://www.aicentralresources.com/badges/featured-badge-dark.svg" alt="Featured on AICentralResources" width="200" height="54" style="border: none;" />
</a>
* Place this HTML snippet in your website's footer, landing page, or press section. This creates a search-friendly backlink directly to your verification page.
Connect with DeepSeek
Frequently Asked Questions
DeepSeek is a Hangzhou-based AI lab that develops open-weight foundation models such as the V4, V3 and R1 families, available through a free chat app, mobile apps and a paid API.
The web chat and apps are free. The API is pay-as-you-go, with V4.1-Flash starting at $0.15 per million input tokens on a cache miss at off-peak rates. Check the official pricing page for current rates.
DeepSeek publishes open model weights on GitHub and Hugging Face. Coverage of the V4 release reports an MIT license, but check each model card for its exact terms.
Yes. It is widely used as the model behind open-source coding agents like Aider and Cline. The older DeepSeek-Coder line was code-specific; the current main models are general-purpose with strong coding ability.
Open weights can be self-hosted, but the largest V4-Pro model is about 1.6 trillion parameters, so most people run smaller or distilled versions locally or use the API.
Similar AI Tools to DeepSeek
View all alternatives of DeepSeek
Qwen2.5-Coder
Alibaba's open-weight code LLM family, 0.5B to 32B, built for local and self-hosted coding
Hugging Face
The AI community platform for hosting, sharing, and running open machine learning models
Fireworks AI
High-performance training and inference platform for open-source AI models
ChatGPT
Engage in dynamic conversations, debug code, and generate creative content with advanced AI.