
Qwen2.5-Coder
Alibaba's open-weight code LLM family, 0.5B to 32B, built for local and self-hosted coding
Gallery
8 items
About Qwen2.5-Coder
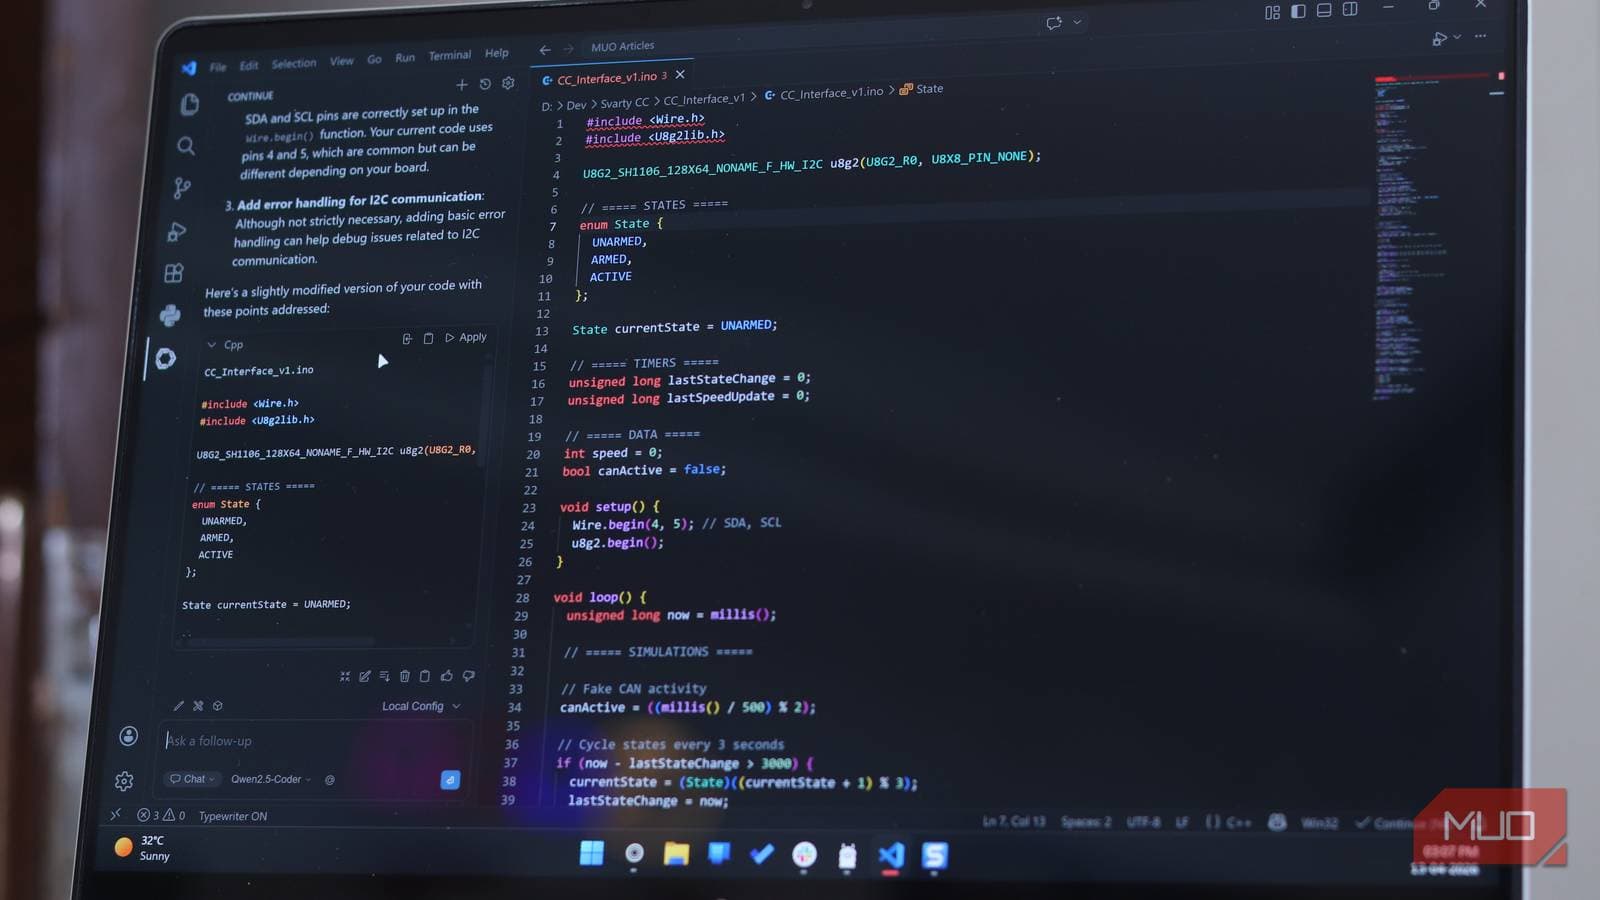
Qwen2.5-Coder is a model family rather than a product, so evaluating it means looking at what the Qwen team has published and how the developer community uses it. The release lists six sizes from 0.5B to 32B, each in Base and Instruct versions, and reports that the 32B Instruct model scores 73.7 on the Aider code-repair benchmark, comparable to GPT-4o at the time, with leading open-model results on EvalPlus, LiveCodeBench and BigCodeBench. These are the vendor's own numbers, and they date from November 2024. Setup is simple because it is supported by Ollama, LM Studio, llama.cpp and vLLM, and plugs into assistants such as Cline, Aider and Kilo Code through an OpenAI-compatible endpoint. The strengths are flexibility and licensing. Most sizes are Apache 2.0, the base models support fill-in-the-middle, which makes the small ones a sensible choice for private autocomplete, and the 7B to 32B models offer 128K context. The limits are age and scope. The Qwen team has since shipped Qwen3-Coder models aimed at agentic coding, and the smaller Qwen2.5-Coder sizes struggle with multi-file edits and tool use. The 3B model also uses the more restrictive Qwen Research license, and the 32B needs serious GPU memory or quantization. The practical recommendation is to treat it as a proven, cheap local default. If you want offline autocomplete or a self-hosted model with no per-token cost and no data leaving your machine, the 7B or 14B is a good fit. If you need the strongest open agentic coding today, evaluate Qwen3-Coder or other recent open models first and keep Qwen2.5-Coder for lightweight, low-latency work.
Qwen2.5-Coder is a family of open-weight code language models from Alibaba's Qwen team, released on November 12, 2024. It ships in six sizes (0.5B, 1.5B, 3B, 7B, 14B and 32B parameters), each with a Base and an Instruct version, so developers can pick a model that fits anything from a laptop to a multi-GPU server. Most sizes are published under Apache 2.0, while the 3B model uses the Qwen Research license.
The family was trained for code generation, code completion, code repair and code reasoning across 40+ programming languages. The flagship Qwen2.5-Coder-32B-Instruct was reported by the Qwen team to score 73.7 on the Aider code-repair benchmark, comparable to GPT-4o, and to lead open-source models on EvalPlus, LiveCodeBench and BigCodeBench. The 7B, 14B and 32B models support 128K-token context, and the base models support fill-in-the-middle completion, which is why they became a common default for editor autocomplete.
It is built for developers, researchers and companies that want to run a coding model on their own hardware through Ollama, LM Studio, llama.cpp or vLLM, or call it through hosted open-model APIs. It plugs into open-source assistants such as Cline, Aider and Kilo Code. Note that the Qwen team has since released newer Qwen3-Coder models, so Qwen2.5-Coder is best seen as a mature, widely supported generation rather than the newest option.
Key Features
- Six model sizes from 0.5B to 32B parameters, each in Base and Instruct versions
- Code generation, completion, repair and reasoning across 40+ programming languages
- Fill-in-the-middle support for editor autocomplete
- 128K-token context on the 7B, 14B and 32B models
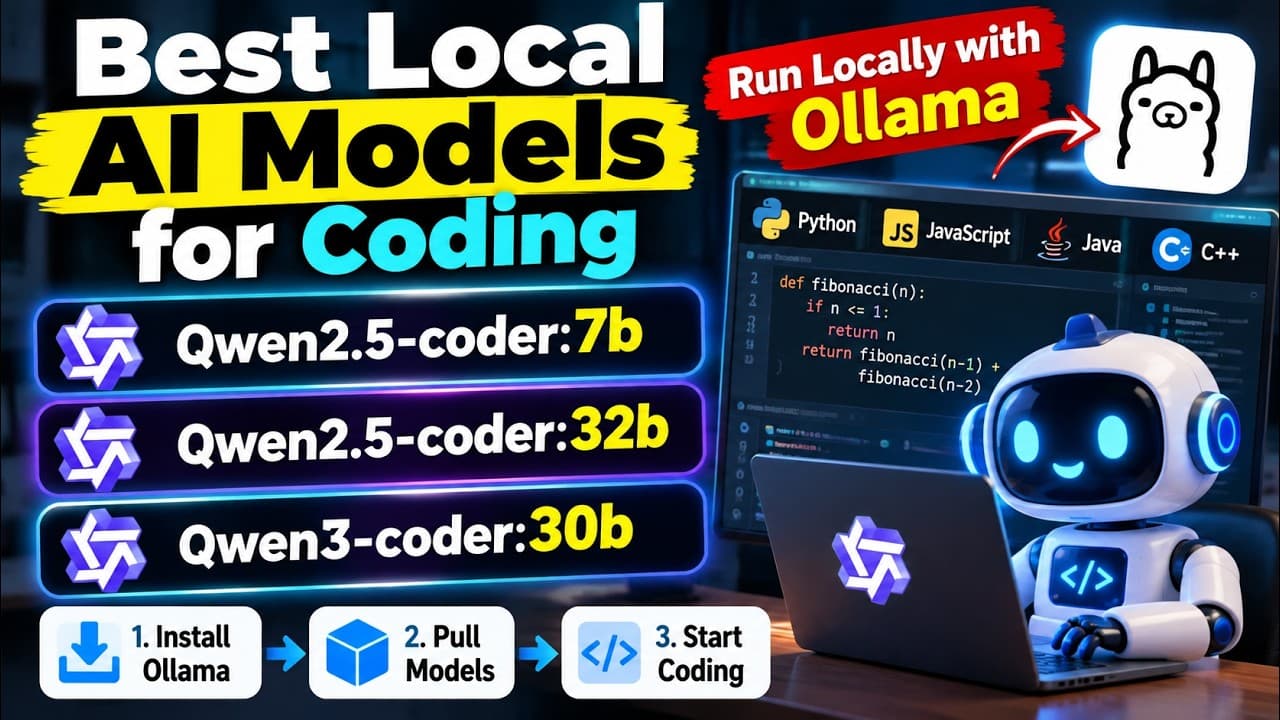
- Runs locally via Ollama, LM Studio, llama.cpp and vLLM
- Quantized GGUF builds for consumer hardware
- Apache 2.0 license on most sizes
- Works as a backend model for Cline, Aider, Kilo Code and similar agents
Pros
- Open weights under Apache 2.0 for most sizes, so it can be self-hosted with no per-token fees
- Flexible size range from phone-class 0.5B to near-frontier 32B
- Strong reported code-repair and generation benchmarks for an open model at release
- Widely supported by local runtimes and open-source coding assistants
- Good fill-in-the-middle autocomplete for private, offline coding
Cons
- Superseded by newer Qwen3-Coder models that handle agentic coding better
- The 3B model uses a more restrictive Qwen Research license
- The 32B model needs a high-memory GPU or quantization for local use
- Smaller sizes are noticeably weaker on complex multi-file or agentic tasks
- It is a model, not a product, so you need a separate editor plugin or agent to use it
Pricing
Qwen2.5-Coder is free to download and run. The 0.5B, 1.5B, 7B, 14B and 32B models are released under Apache 2.0, and the 3B model uses the Qwen Research license, so check it before commercial use. There is no subscription from the Qwen team for the open weights.
Your real cost is hardware or hosting. Small models (0.5B to 7B) run on consumer laptops and GPUs, while the 32B model typically needs a high-memory GPU or quantized builds. Third-party inference providers also host the models and bill per million tokens, at rates that vary by provider and change often, so verify on the provider's pricing page.
There is no enterprise tier for the open weights. Companies that want managed access can use Alibaba Cloud's hosted Qwen offerings, which are priced separately.
Claim Verified Creator Badge
Are you the founder of Qwen2.5-Coder? Display this listing's verified badge on your website to show your customers that your product has been vetted and listed on AI Central Resources.
<a href="https://www.aicentralresources.com/tool/qwen25-coder" target="_blank" rel="noopener">
  <img src="https://www.aicentralresources.com/badges/featured-badge-dark.svg" alt="Featured on AICentralResources" width="200" height="54" style="border: none;" />
</a>
* Place this HTML snippet in your website's footer, landing page, or press section. This creates a search-friendly backlink directly to your verification page.
Connect with Qwen2.5-Coder
Frequently Asked Questions
Qwen2.5-Coder is a family of open-weight code language models from Alibaba's Qwen team, released in November 2024 in 0.5B, 1.5B, 3B, 7B, 14B and 32B sizes.
Most sizes (0.5B, 1.5B, 7B, 14B, 32B) use Apache 2.0, which allows commercial use. The 3B model uses the Qwen Research license, so review its terms first.
Yes. It runs through Ollama, LM Studio, llama.cpp and vLLM. The 7B and 14B models suit consumer GPUs, while the 32B model usually needs a high-memory GPU or a quantized build.
Yes. The Qwen team has released the Qwen3-Coder family, including Qwen3-Coder-30B-A3B and Qwen3-Coder-480B-A35B, aimed at agentic coding. Qwen2.5-Coder remains popular for lightweight local use.
Any tool that accepts an OpenAI-compatible or Ollama endpoint can use it, including Cline, Aider and Kilo Code, as well as editor autocomplete plugins.
Similar AI Tools to Qwen2.5-Coder
View all alternatives of Qwen2.5-Coder
Hugging Face
The AI community platform for hosting, sharing, and running open machine learning models
Fireworks AI
High-performance training and inference platform for open-source AI models
Refact.ai
Open-source AI coding agent — self-hosted, fine-tuned on your codebase, #1 SWE-bench
Tabnine
The original AI code assistant — private, secure, and built for the enterprise